Blog
Notes on scheduled jobs, monitoring, and the failure modes that never announce themselves.
Sep 11, 2026
Scheduled Web Scraping API: A Reliable Cron Blueprint
Why 'Just Add Cron' Breaks Headless Browser Jobs Cron feels solved. Add a line to crontab, point it at a script that boots Puppeteer or Playwright, and walk away. It works for a week. Then memory clim…
Sep 11, 2026
Full Page Screenshot API: Fixing Lazy Load & Sticky Headers
Most tutorials on capturing a full page screenshot show a single line — fullPage: true — and call it done. In production, that's where trouble starts. Screenshot pipelines that work in a demo start re…
Sep 11, 2026
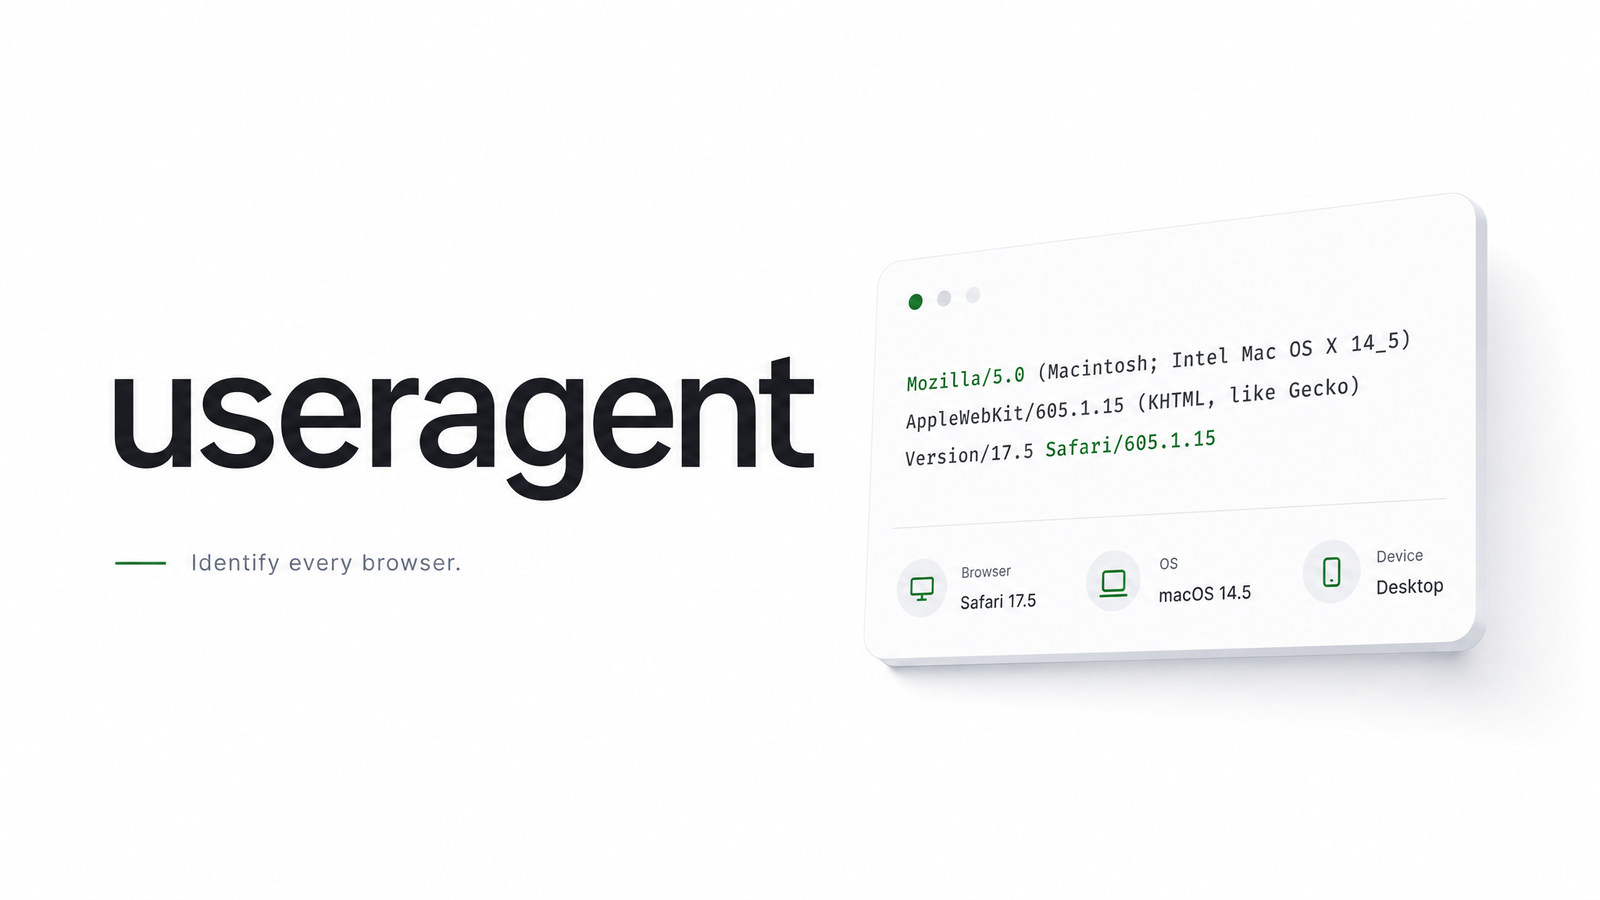
User Agent Explained: Why Yours Is Probably Leaking
Every HTTP request carries a small, easily overlooked header that tells the server what's asking: browser, engine, OS, sometimes device. That's the user agent, and for anyone running headless browsers…
Sep 10, 2026
Puppeteer to API Migration: A Step-by-Step Runbook
Most articles about ditching self-hosted Puppeteer or Playwright sell you on the idea and stop there. This one is an actual migration runbook: audit what your script does today, map each method call t…
Sep 10, 2026
Web Scraping Legality: A Decision Framework for Engineers
There's No Single 'Web Scraping Law' Ask "is web scraping legal?" and the honest answer is: it depends. Legality isn't governed by one statute — it sits at the intersection of contract law (terms of s…
Sep 10, 2026
GraphQL Query Scraping: Read, Replay, and Know When to Stop
What a GraphQL Query Actually Is (And Why It Shows Up in Scraping) A GraphQL query is a request written in a query language for APIs that asks for exactly the fields a client needs, in one round trip,…
Sep 9, 2026
ProxyScrape Free Proxy: What It Really Delivers
Typing "proxyscrape free proxy" into a search bar usually means one thing: you're deciding whether to spend engineering time integrating a free tool before reaching for something paid. Free proxy list…
Sep 9, 2026
Free Proxy Scraper: What It Means and When It Breaks
Search for "free proxy scraper" and you'll land on two different things: a tool that harvests lists of free proxy IPs, and developers describing the practice of scraping websites through free proxies.…
Sep 9, 2026
Is Web Scraping Legal? The Case Law That Decides It
Ask ten lawyers "is web scraping legal" and you'll get ten versions of "it depends." That's accurate, because no single statute answers the question. This article walks through the actual rulings that…
Sep 8, 2026
Is Screen Scraping Legal? The Developer's Answer
The Quick Answer Screen scraping itself is not illegal. No U.S. or EU statute bans extracting data from a rendered page — your legal exposure depends on how you access the data, what the data is, and…
Sep 8, 2026
Is Scraping Websites Legal? A Developer's Risk Guide
The Short Answer Scraping publicly available data is generally legal in the US. Is web scraping illegal? Not by default — the legal risk is a function of four variables: what you scrape, whether you a…
Sep 8, 2026
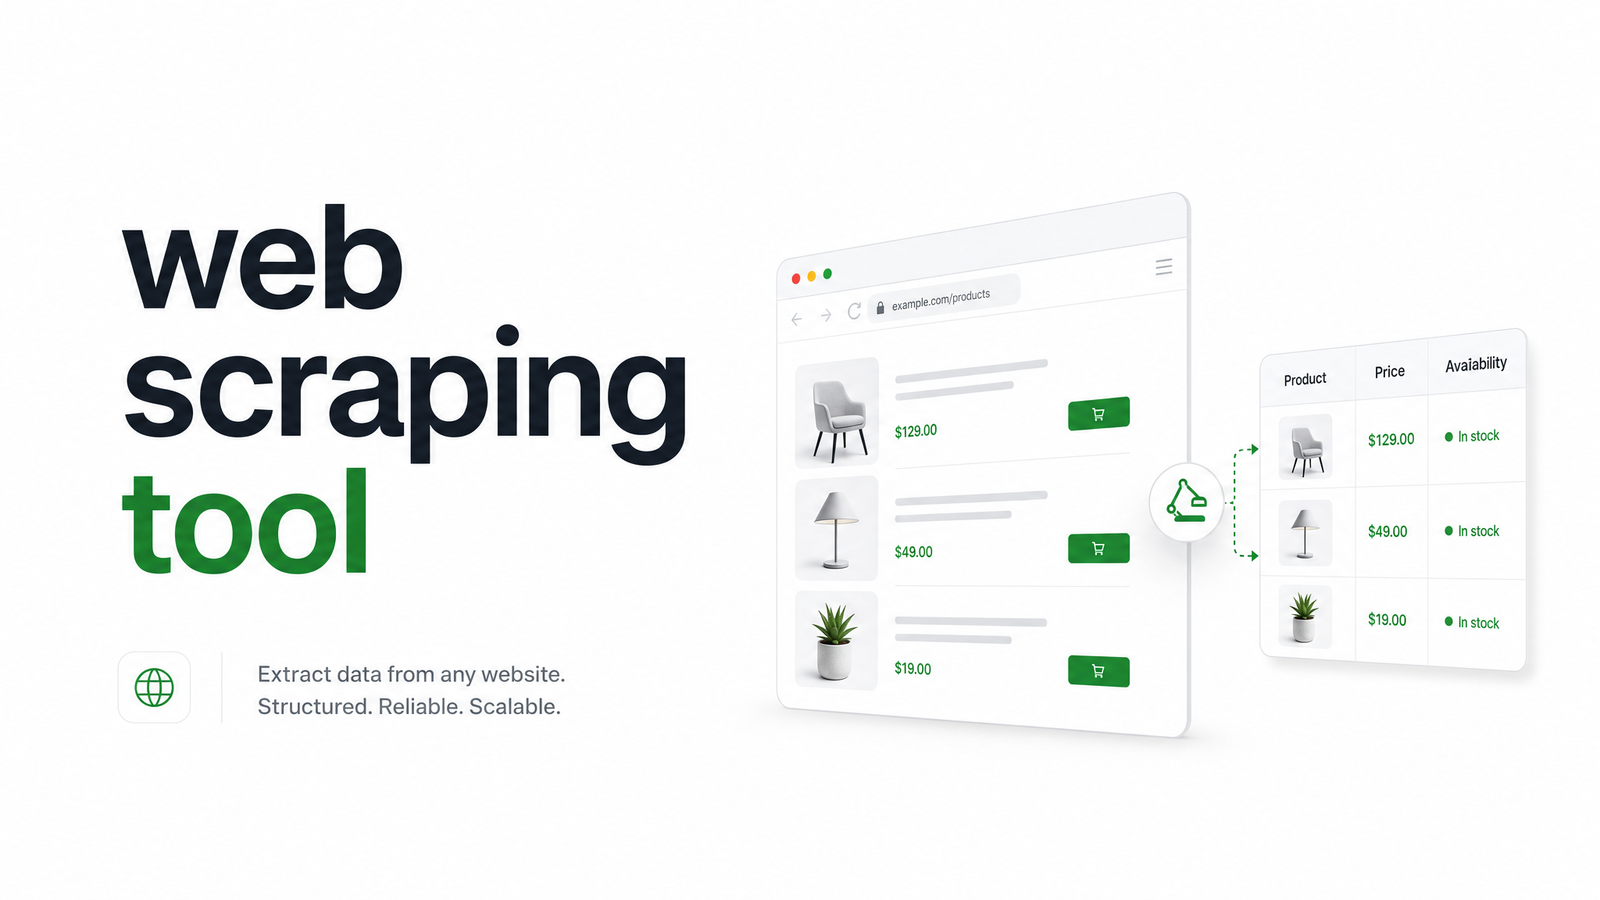
Web Scraping Tool: The Developer's Category Map (2026)
What Is a Web Scraping Tool? A web scraping tool is software that automates pulling data from websites — fetching pages, rendering content, and extracting structured information instead of copying it…
Sep 7, 2026
Bot Detection Headless Browser: How to Spot a Block
When Your Scraper Doesn't Know It Got Blocked A headless browser request comes back with HTTP 200 and a full HTML body. Your pipeline marks it as success, extracts whatever fields it can find, and mov…
Sep 7, 2026
HTML to PDF vs Screenshot API: Which Endpoint to Call
Picking between an HTML-to-PDF API and a screenshot API isn't really about file format — it's about which rendering primitive Chrome uses to produce that file. Get the primitive wrong and you'll fight…
Sep 7, 2026
Headless Browser Timeout Handling: A Resilience Pattern
Why Naive Timeouts and Retries Break Down for Headless Browser Rendering A render job is not a cheap idempotent HTTP GET. When a normal REST call times out, retrying costs one more request. When a hea…
Sep 6, 2026
Webhook API Async Job Patterns for Headless Browser Tasks
Why Polling Breaks Down for Long-Running Browser Jobs Rendering a heavy single-page app, generating a multi-page PDF, or scraping a site behind a queue doesn't take a fixed amount of time. It might fi…
Sep 6, 2026
Rotating Proxies vs Browser Sessions: A Scraper's Framework
Two Different Problems, One Symptom: Getting Blocked When a scraping job starts failing, the reflexive fix is "rotate more IPs." Sometimes that works. Often it doesn't — teams burn budget on residenti…
Sep 6, 2026
How to Render JavaScript for Scraping SPAs Reliably
Scraping a modern single page application isn't a parsing problem — it's a timing problem. The HTML your scraper needs doesn't exist until JavaScript runs, and knowing exactly when that JavaScript is…
Sep 5, 2026
How to Scrape Data Behind a Login (Without Breaking It)
Why Scraping Behind a Login Is a Different Problem Than Public Scraping Scraping a public product listing and scraping data behind a login are different engineering problems wearing similar clothes. P…
Sep 5, 2026
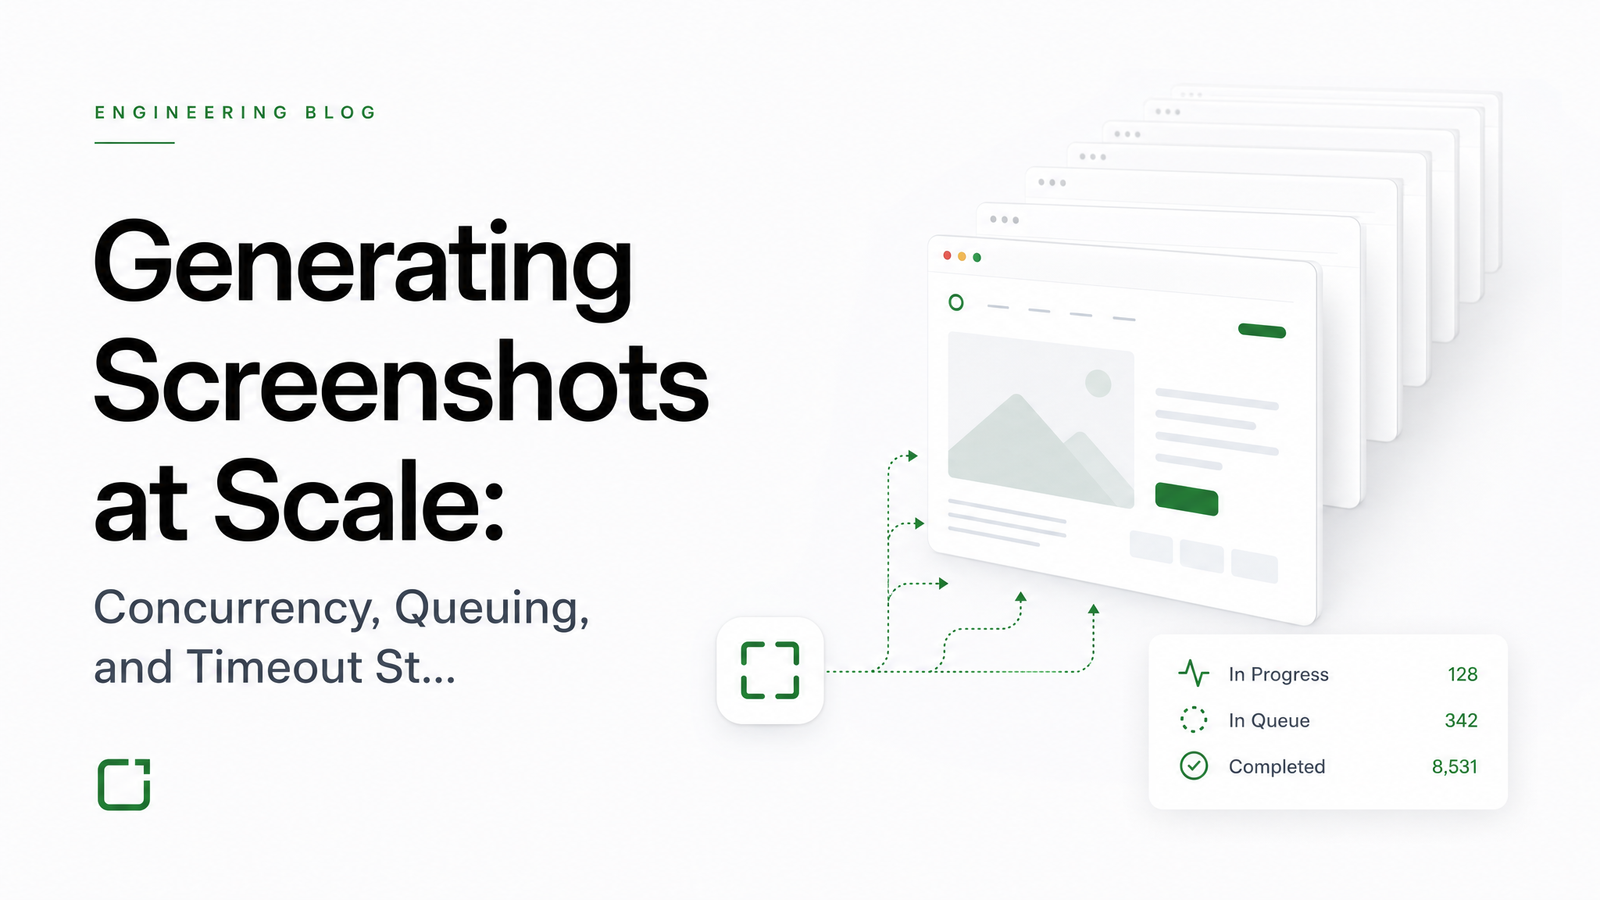
Screenshot API at Scale: A Concurrency & Queue Playbook
Why Screenshot Volume Breaks Naive Architectures A script that launches Puppeteer or Playwright, opens a page, and saves a screenshot works fine at ten requests a day. Run it at ten thousand a day and…
Sep 5, 2026
HTML to PDF API: How to Get Pixel-Perfect Output
Why HTML-to-PDF Output Breaks (Even in a Real Browser) Every HTML-to-PDF API does the same fundamental thing: takes a live browser render and freezes it into a fixed, paginated document. That's why fi…
Sep 4, 2026
Python Scraping Tools: The Layer-by-Layer Decision Guide
The Python Scraping Stack: 5 Tools, 5 Different Jobs Ask ten developers which python scraping tools to use and you'll get ten opinions, mostly because the question is incomplete. Scraping isn't one ta…
Sep 4, 2026
Dynamic Content Scraping: Why Pages Load Blank & How to Fix
Why Your Scraper Sees an Empty Page (And the Site Doesn't) You open the page in a browser and everything is there — prices, reviews, product grids. You point curl or Python's requests at the same URL…
Sep 4, 2026
Bypass CAPTCHA the Right Way: Avoid the Trigger, Not the
Developers searching for how to bypass CAPTCHA usually want a quick technical fix or reassurance they're not breaking the law. This article gives you both — the honest version, not the affiliate-link…
Sep 3, 2026
Headless Chrome API: What It Means and How to Use One
Search for "headless Chrome API" and you'll land on either dense protocol-level Chrome DevTools documentation or a Puppeteer tutorial that never uses "API" the way a backend developer means it. Neithe…
Sep 3, 2026
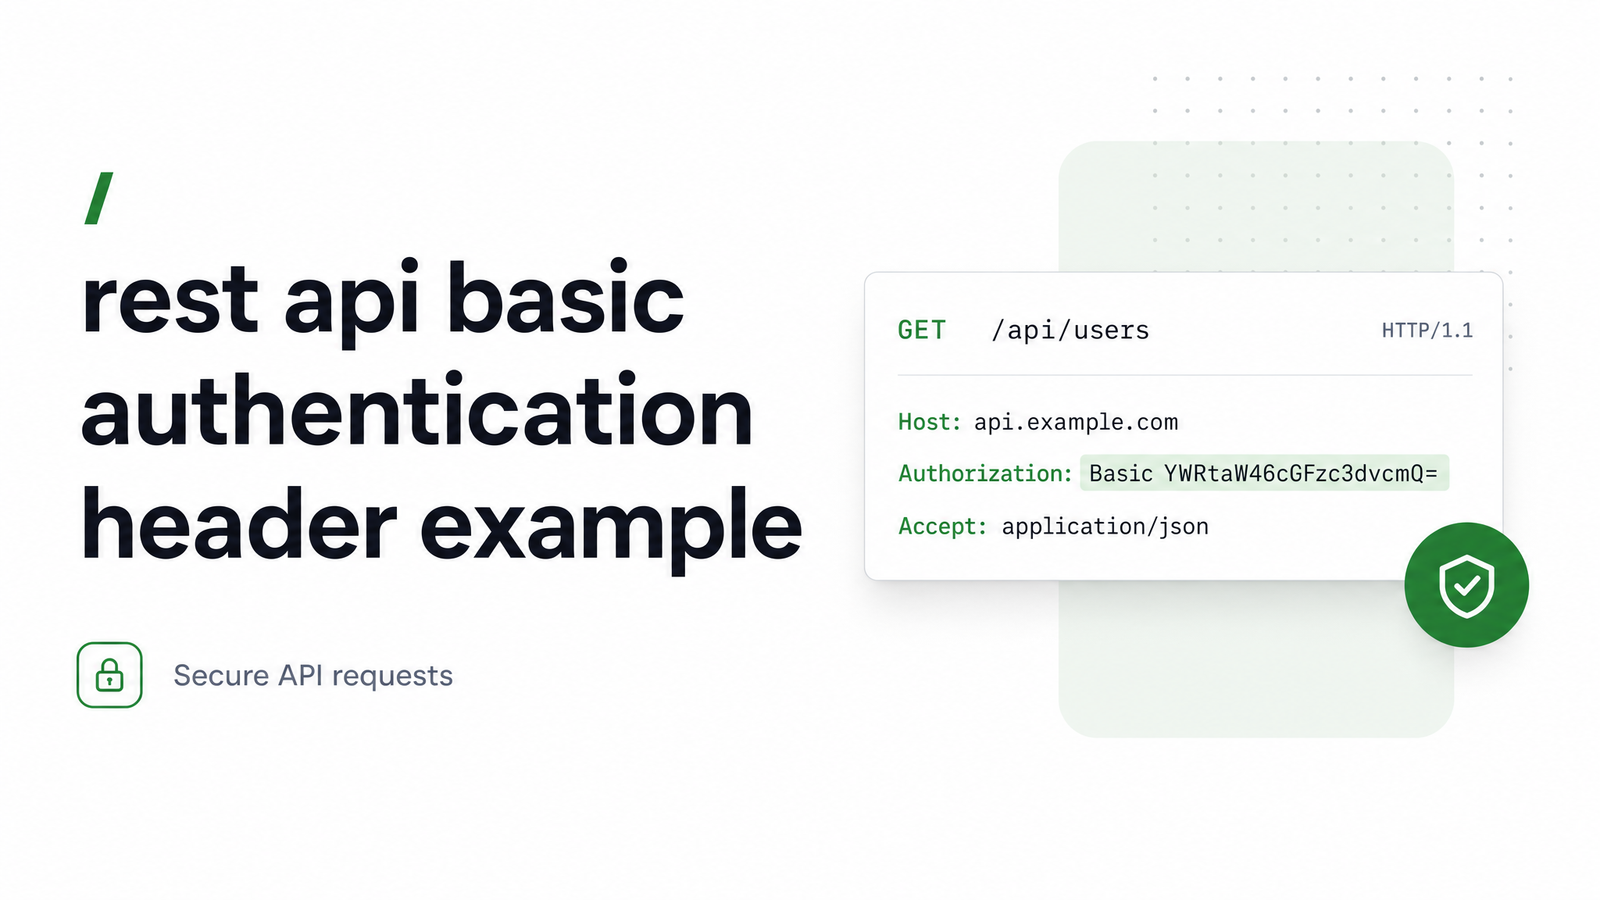
REST API Basic Authentication Header Example (RFC 7617)
What a Basic Auth Header Actually Looks Like On the wire, a Basic Authentication header is a single line sent with every request: Authorization: Basic QWxhZGRpbjpvcGVuIHNlc2FtZQ== That's the canonical…
Sep 3, 2026
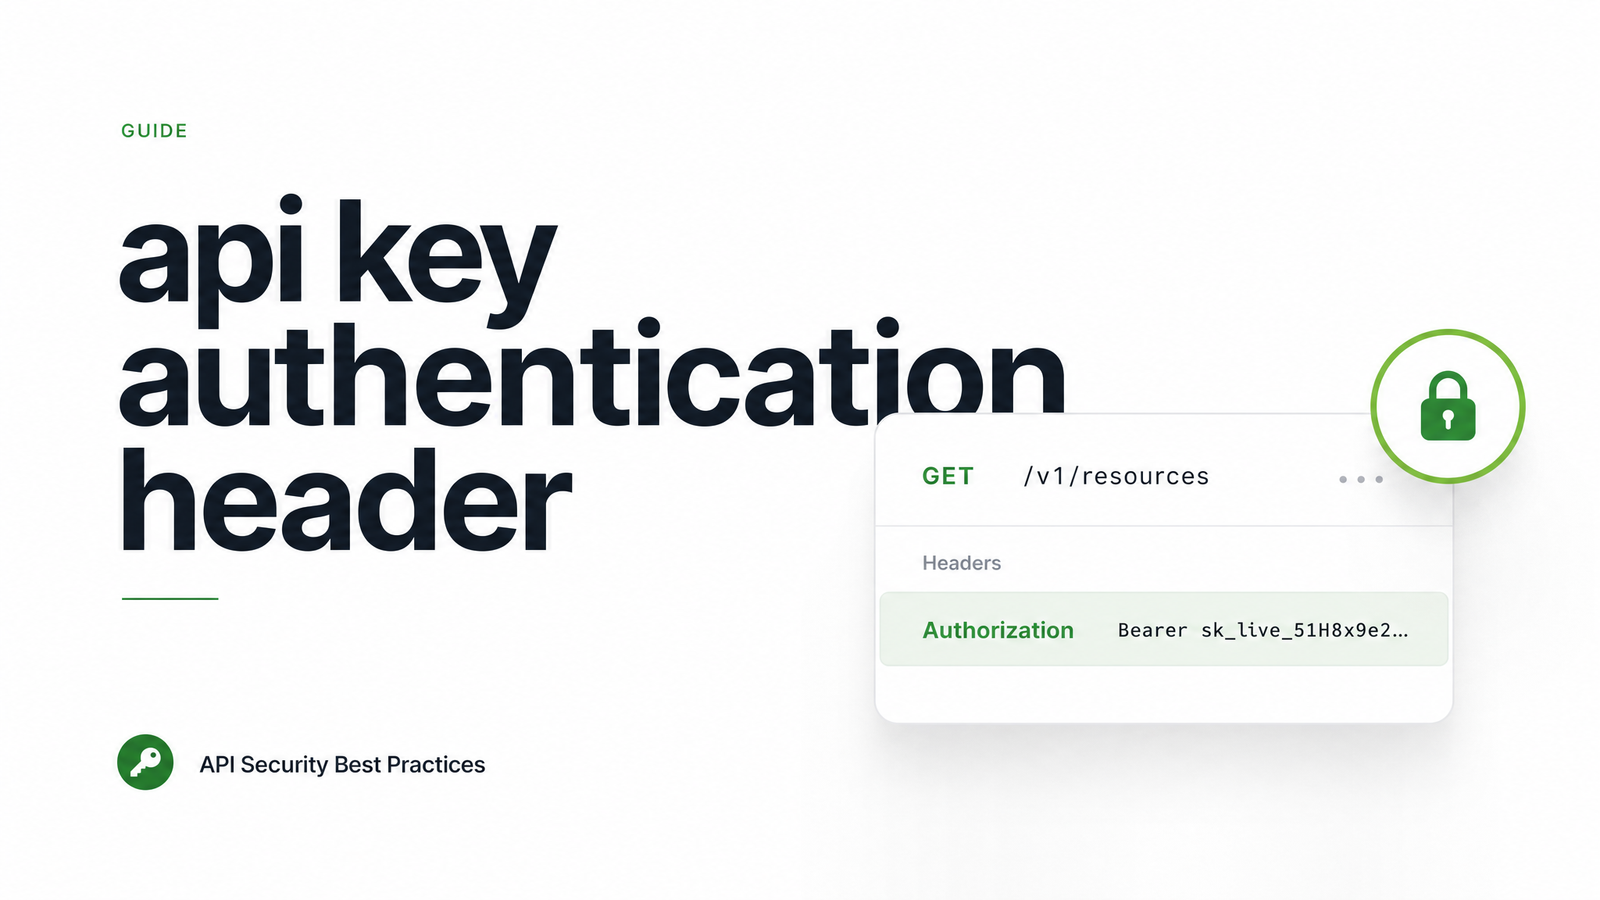
API Key Authentication Header: Format, Examples, Fixes
Every API call to a headless browser service, or any authenticated API, needs a credential attached to it — and the single most common integration failure is sending that credential in the wrong place…
Sep 2, 2026
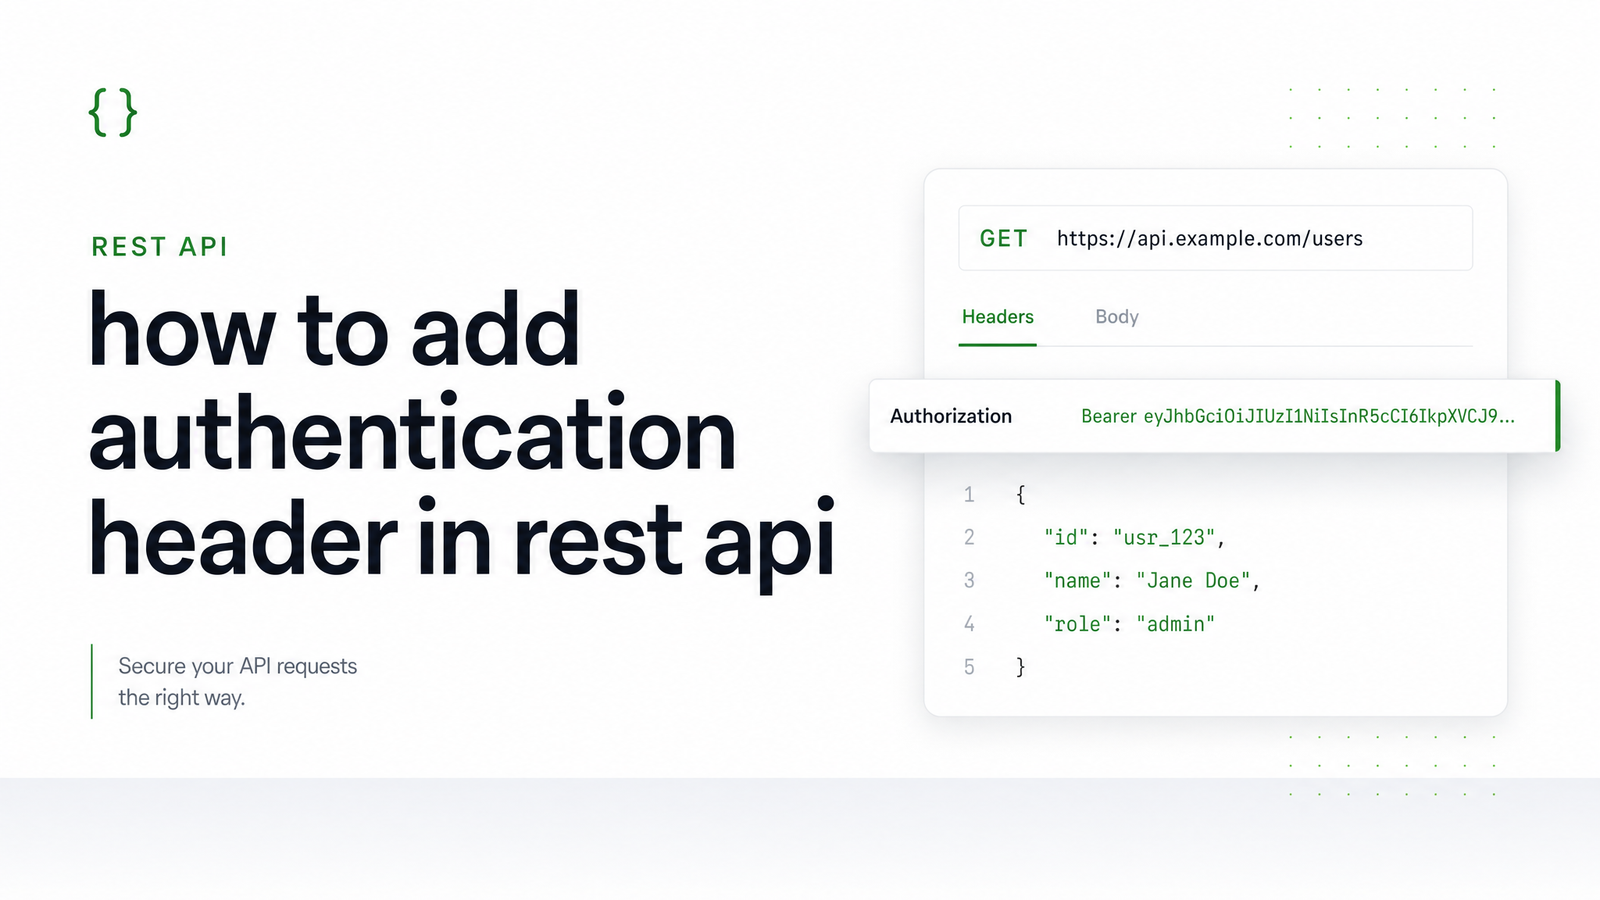
How to Add an Authentication Header in a REST API
Most failed API calls aren't caused by bad credentials — they're caused by a header that never made it onto the request correctly. Adding an authentication header is a one-line change in most tools, b…
Sep 2, 2026
Web API Authentication Token Header: A Practical Guide
What Is a Web API Authentication Token Header? A web API authentication token header is an HTTP header — almost always Authorization — that carries a credential proving your request is allowed to hit…
Sep 2, 2026
Website Scrapers: The Developer's Framework for Choosing
What People Mean by 'Website Scrapers' A website scraper extracts data from a web page and turns it into structured output — a spreadsheet row, a JSON object, a screenshot, a PDF. A crawler discovers…
Sep 1, 2026
GraphQL API Explained: How to Find and Scrape One
What Is a GraphQL API? A GraphQL API is a query language and runtime for APIs that exposes a single endpoint through which clients request exactly the data they need, described by a strongly typed sch…
Sep 1, 2026
PDF Generation API: A Developer's Build vs. Buy Guide
What a PDF Generation API Actually Does A PDF generation API is an HTTP endpoint you call with either a URL or a raw HTML string, and it returns a rendered PDF file. Send markup, get bytes. No client…
Sep 1, 2026
Gemini Developer API Pricing in 2026: The Real Cost Guide
Gemini developer API pricing runs on a pay-per-token model, split by input and output tokens, with rates that shift depending on model tier and prompt size. If you're piping rendered HTML, screenshots…
Aug 31, 2026
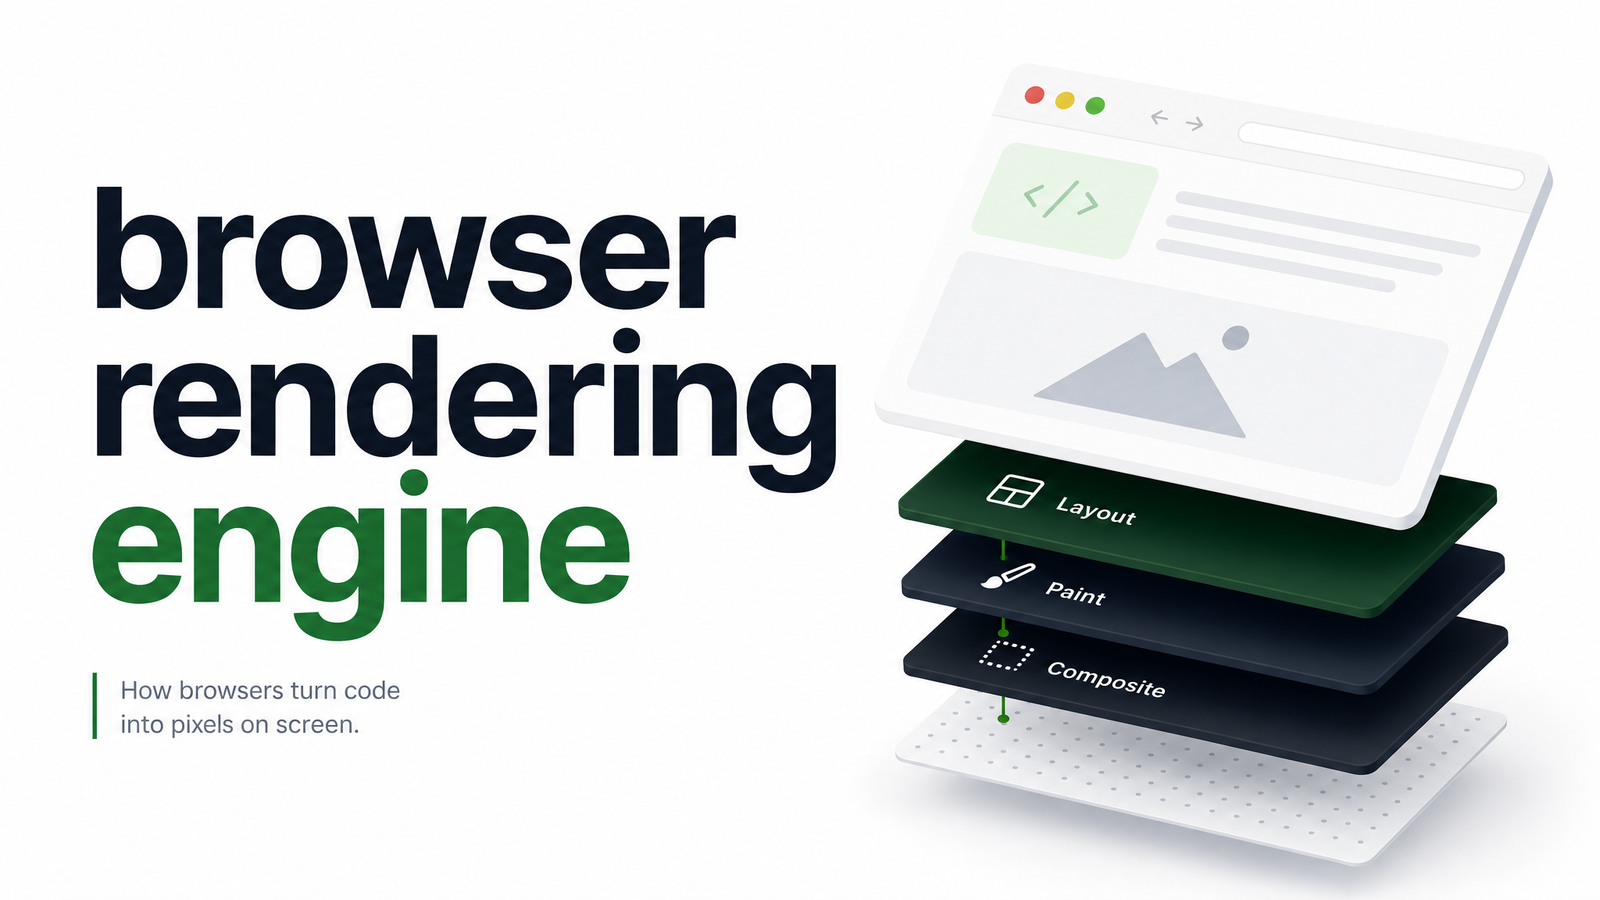
Browser Rendering Engine, Explained for Backend Developers
Most explanations of the browser rendering engine target front-end developers debugging Safari quirks. If you're calling a rendering engine programmatically — for screenshots, PDFs, or scraping at sca…
Aug 31, 2026
Web Application Automation Testing: A Scaling Framework
What Web Application Automation Testing Actually Means Web application automation testing uses code to drive a browser through scripted, repeatable interactions — clicking, typing, navigating, asserti…
Aug 31, 2026
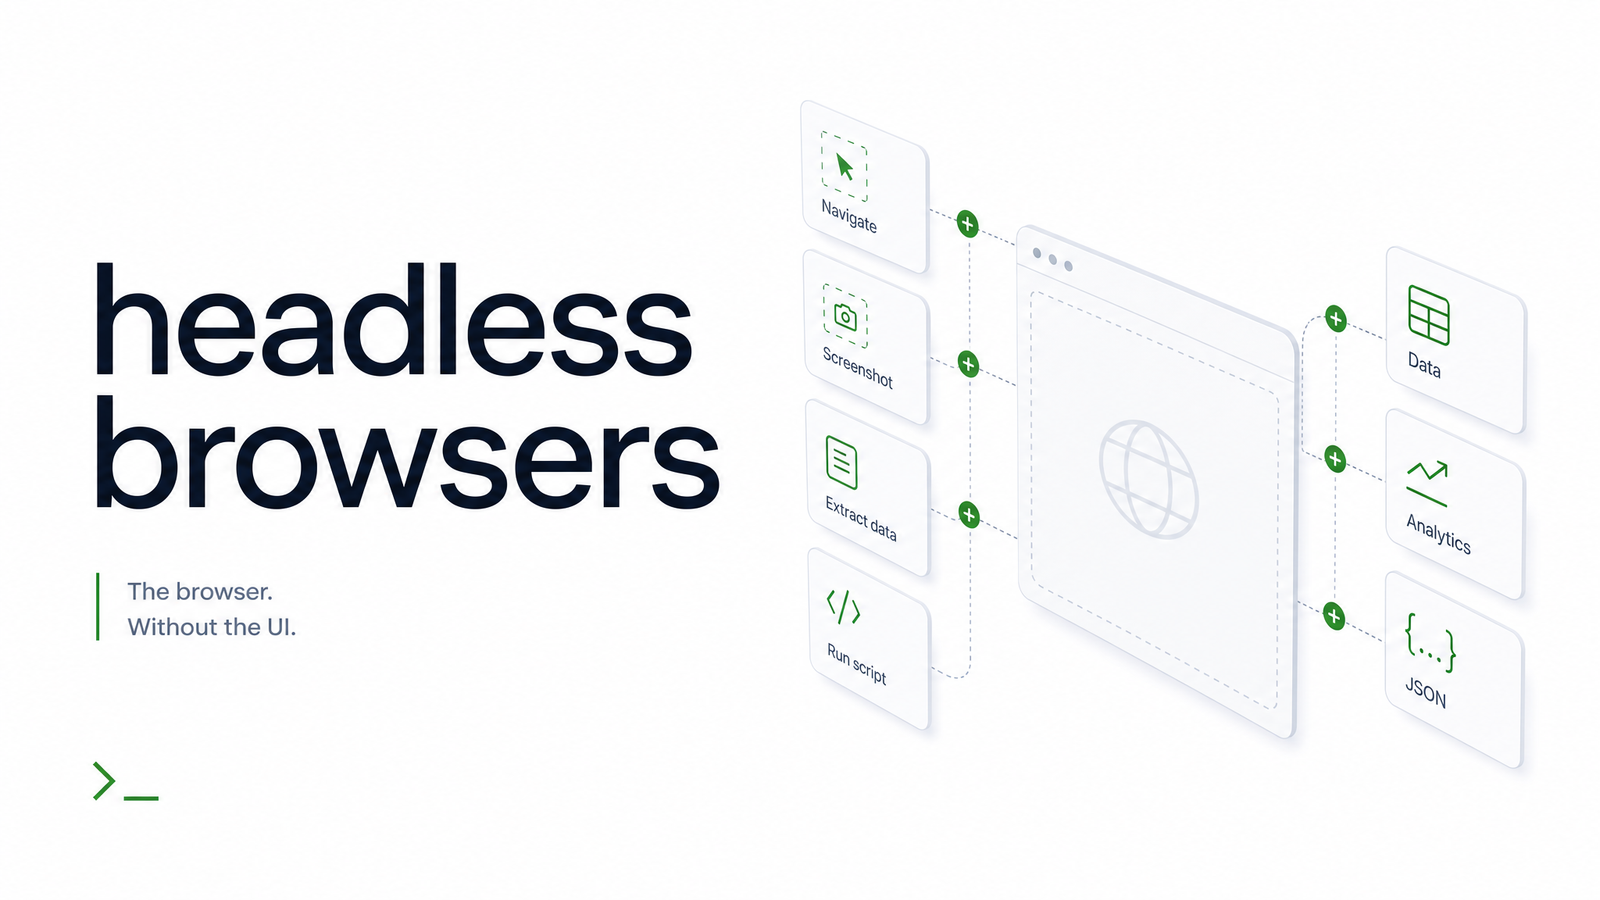
Headless Browsers Explained: Definition, Uses, and Costs
What Is a Headless Browser? A headless browser is a real browser engine — Chromium, Firefox, or WebKit — running without a visible window or GUI, controlled through code or a protocol like the Chrome…
Aug 30, 2026
Browserless Chromium: Disambiguating the Term for Developers
What "Browserless Chromium" Actually Means Search for "browserless chromium" and you'll find the phrase treated as a single buzzword. It isn't — it's two ideas that collide in one query. The first is…
Aug 30, 2026
Browserless MCP: How It Works and When to Build Your Own
AI assistants like Claude and coding agents in Cursor or Windsurf reason well but can't see the live web unless someone gives them a way to. The Model Context Protocol closes that gap, and Browserless…
Aug 30, 2026
How to Scrape Website Data: Methods, Legality, Tools
What Counts as "Scraping Website Data" (and Why the Method Matters) To scrape website data means pulling structured information off a web page programmatically instead of copying it by hand — prices,…
Aug 29, 2026
API Rate Limiting Best Practices for Providers and Clients
Rate limiting fails in two directions. Providers either lock down their API so hard that legitimate bursts get punished, or leave it so loose that a handful of misbehaving clients take the whole syste…
Aug 29, 2026
Web Scraper Explained: How It Works and When to Upgrade
What Is a Web Scraper? A web scraper is a program that requests a web page and extracts specific pieces of data from it — prices, listings, headlines, table rows — instead of a human copying them by h…
Aug 29, 2026
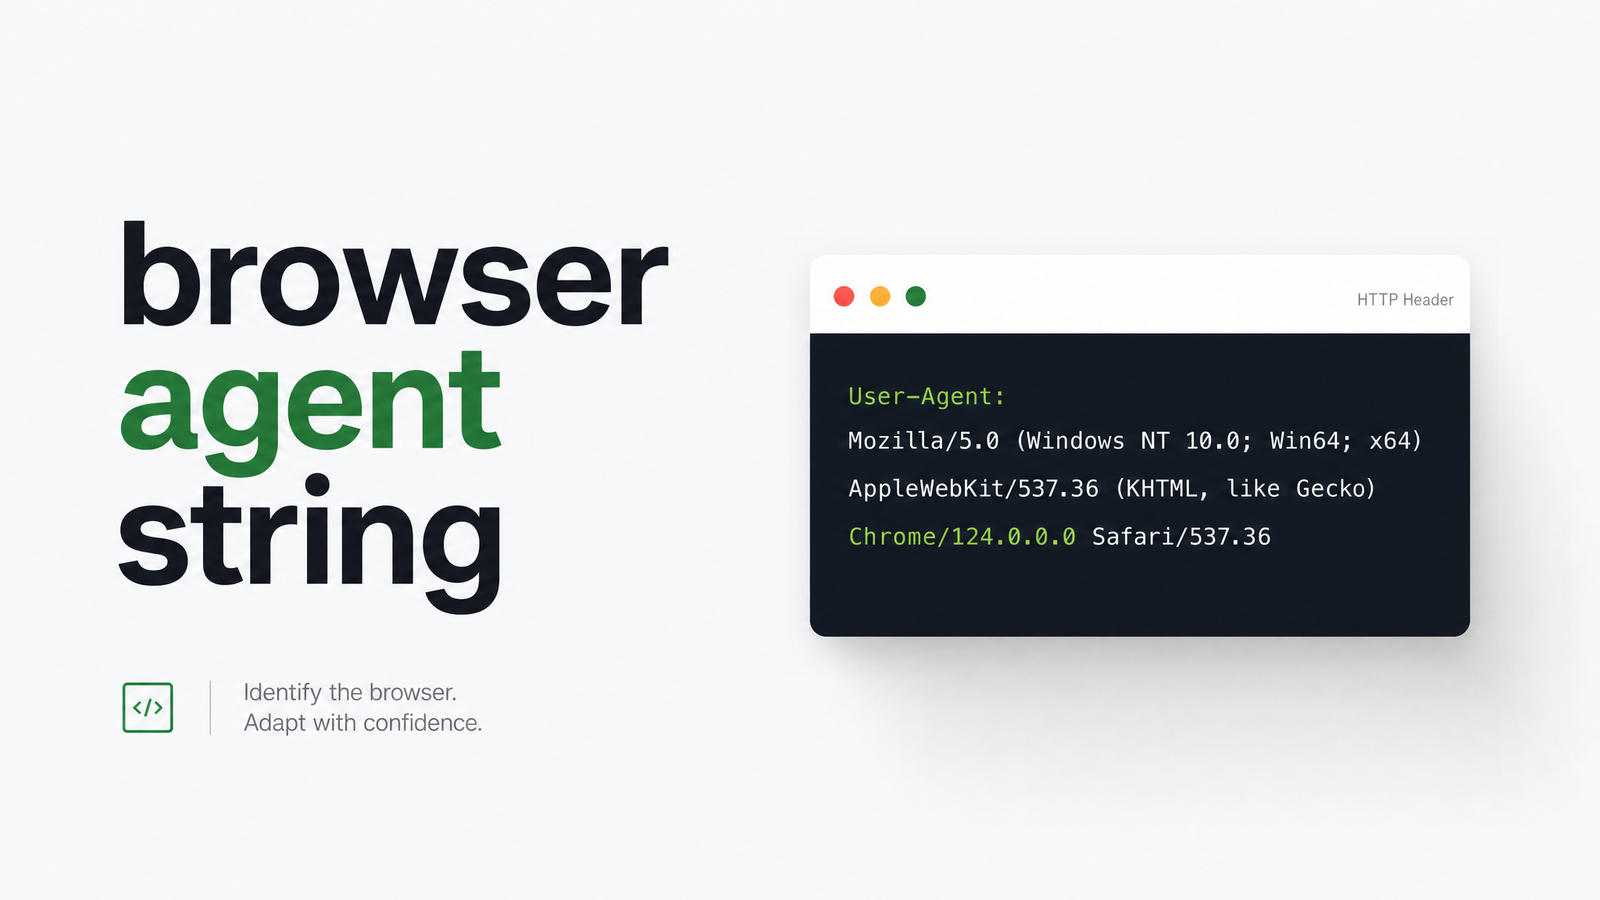
Browser Agent String: The Engineering Guide for Scraping
What Is a Browser Agent String? A browser agent string — more commonly called a User-Agent string — is a plain text header identifying the client making an HTTP request: browser, rendering engine, OS,…
Aug 28, 2026
Screenshot API: What It Is and How to Choose One
A screenshot API turns a URL into an image (or PDF) by rendering it in a real browser engine and returning the output over HTTP. The details of how a provider handles rendering, waiting, and page quir…
Aug 28, 2026
Automated Web Browsing: What It Is and How It Works
What Is Automated Web Browsing? Automated web browsing is the use of code to control a browser instead of a person clicking, typing, and scrolling. A script opens a page, waits for content to load, cl…
Aug 28, 2026
Puppeteer Alternative: Library vs. Infrastructure Decision
Why Developers Look for a Puppeteer Alternative Puppeteer is a solid library. Most teams searching for a puppeteer alternative aren't unhappy with the API — they're unhappy with what happens after the…
Aug 27, 2026
Docker Browserless: Full Setup Guide + Self-Host Decision
What Is Browserless (and Why Run It in Docker)? Browserless is a headless Chrome/Chromium service you talk to over WebSocket or REST instead of installing and managing a browser binary yourself. Send…
Aug 27, 2026
Browserless API Key: How to Get, Use, and Rotate It
What Is a Browserless API Key? A Browserless API key is the per-account credential that authenticates every request to Browserless's REST and WebSocket/CDP endpoints. Whether you're driving headless C…
Aug 27, 2026
n8n Browserless: 3 Ways to Add Headless Browser Rendering
Does n8n Have a Browserless Node? (Short Answer) No — n8n does not ship a native browserless node. Searching your node panel for "headless browser" or "screenshot" turns up nothing. What you actually…
Aug 26, 2026
Browserless Alternatives: What to Switch to and Why
Developers rarely look for Browserless alternatives out of curiosity. They look because a bill came in higher than expected, a production job got throttled by concurrency limits, or someone spent a we…
Aug 26, 2026
Captcha Solver Explained: How They Work, and Alternatives
What Is a Captcha Solver? A captcha solver is a service or tool that automates the challenge-response step a CAPTCHA demands, so a script keeps running without a human clicking checkboxes or typing di…